Dedicated AI compute, built and run for you.
TensorCove designs, builds and operates private GPU clusters for AI companies and enterprises, on our power or at your site, and runs them around the clock under a service-level agreement.
Shared cloud capacity is scarce. Building your own data center takes years. A dedicated cluster gives you the middle path.
Predictable performance
Your GPUs, your network fabric and your storage. No noisy neighbors and no surprise capacity limits.
Predictable cost
A fixed contract for dedicated capacity, so you can plan training runs and inference growth with confidence.
No infrastructure burden
We handle power, cooling, procurement, installation and operations. Your team stays focused on models and products.
One partner, from design to daily operations.
We design, build and run the cluster. You get dedicated capacity.
See all services
Cluster design
Architecture fit to your workload: GPU platform, network fabric, storage and facility, sized for training, inference or both.
Build and deploy
We procure the full stack, install and integrate it, and validate performance before we hand the cluster over.
Managed operations
24/7 monitoring, alerting and on-site response, with reporting that plugs into your own tools.
SLA assurance
Redundant design, spare parts on hand and fast replacement paths behind every service commitment.
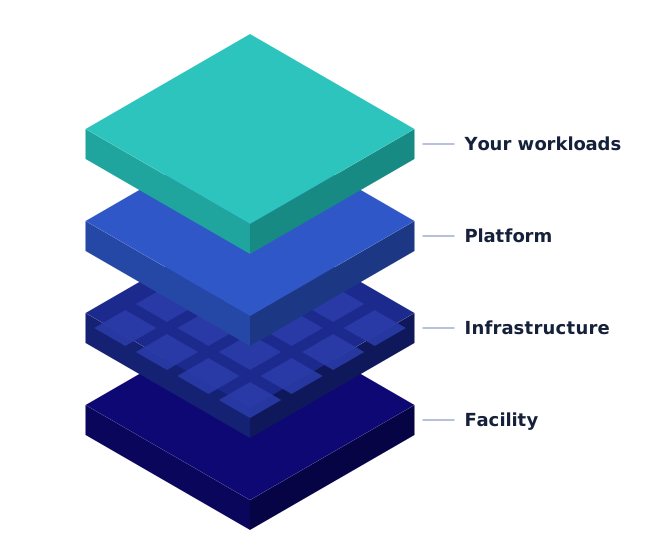
Engineered from the data hall to your workloads.
One integrated design across power, cooling, GPUs, networking and the software platform, so every layer works together from day one. Your models and data stay yours.
- NVIDIA B300, GB300 and Vera Rubin, as available, plus AMD options
- InfiniBand or Spectrum-X fabric, liquid or air cooling
- NVIDIA AI Enterprise, Run:ai, Kubernetes or Slurm
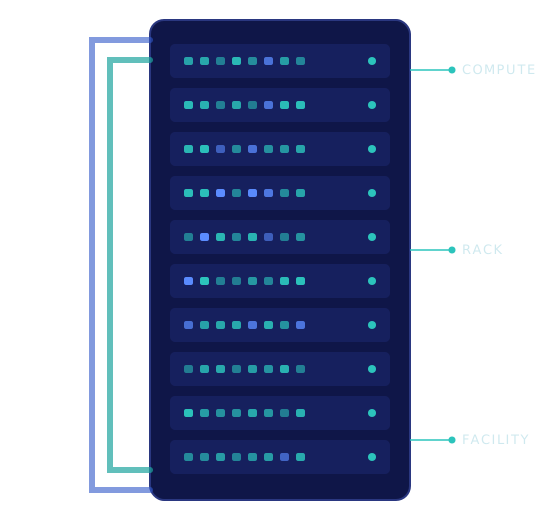
Operated 24/7, from facility to GPU.
We monitor every level around the clock and act on alerts before they affect your workloads.
- Facility: power, cooling and physical security
- Rack: power per circuit, coolant flow and temperature
- Compute: GPU, node and network fabric health
- Redundant (N+1) power and cooling, spares on hand, rapid on-site dispatch
Ready to plan your cluster?
Tell us about your workload and timeline. We will come back with a cluster design and a proposal.